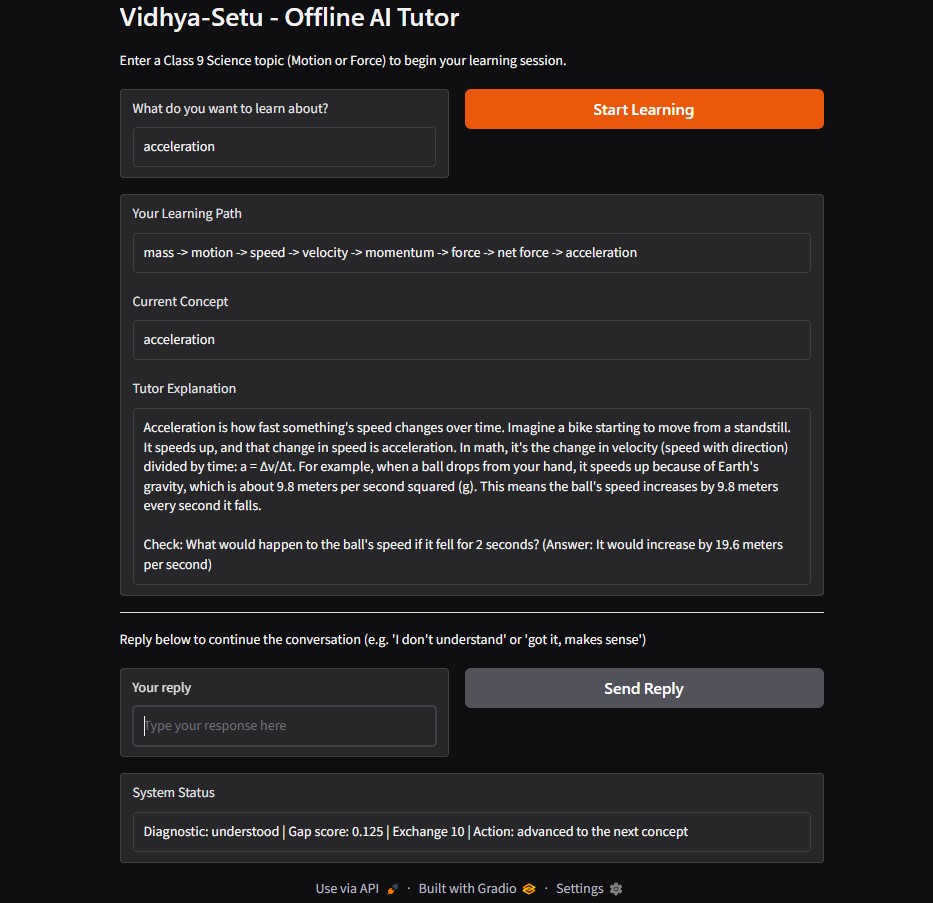
Local AI application
RecruitSheriff
From a requirement to a reason.
Qwen3-4B · QLoRA · Unsloth
Edited walkthrough of supplied screenshots. Candidate identifiers are masked in the source captures.
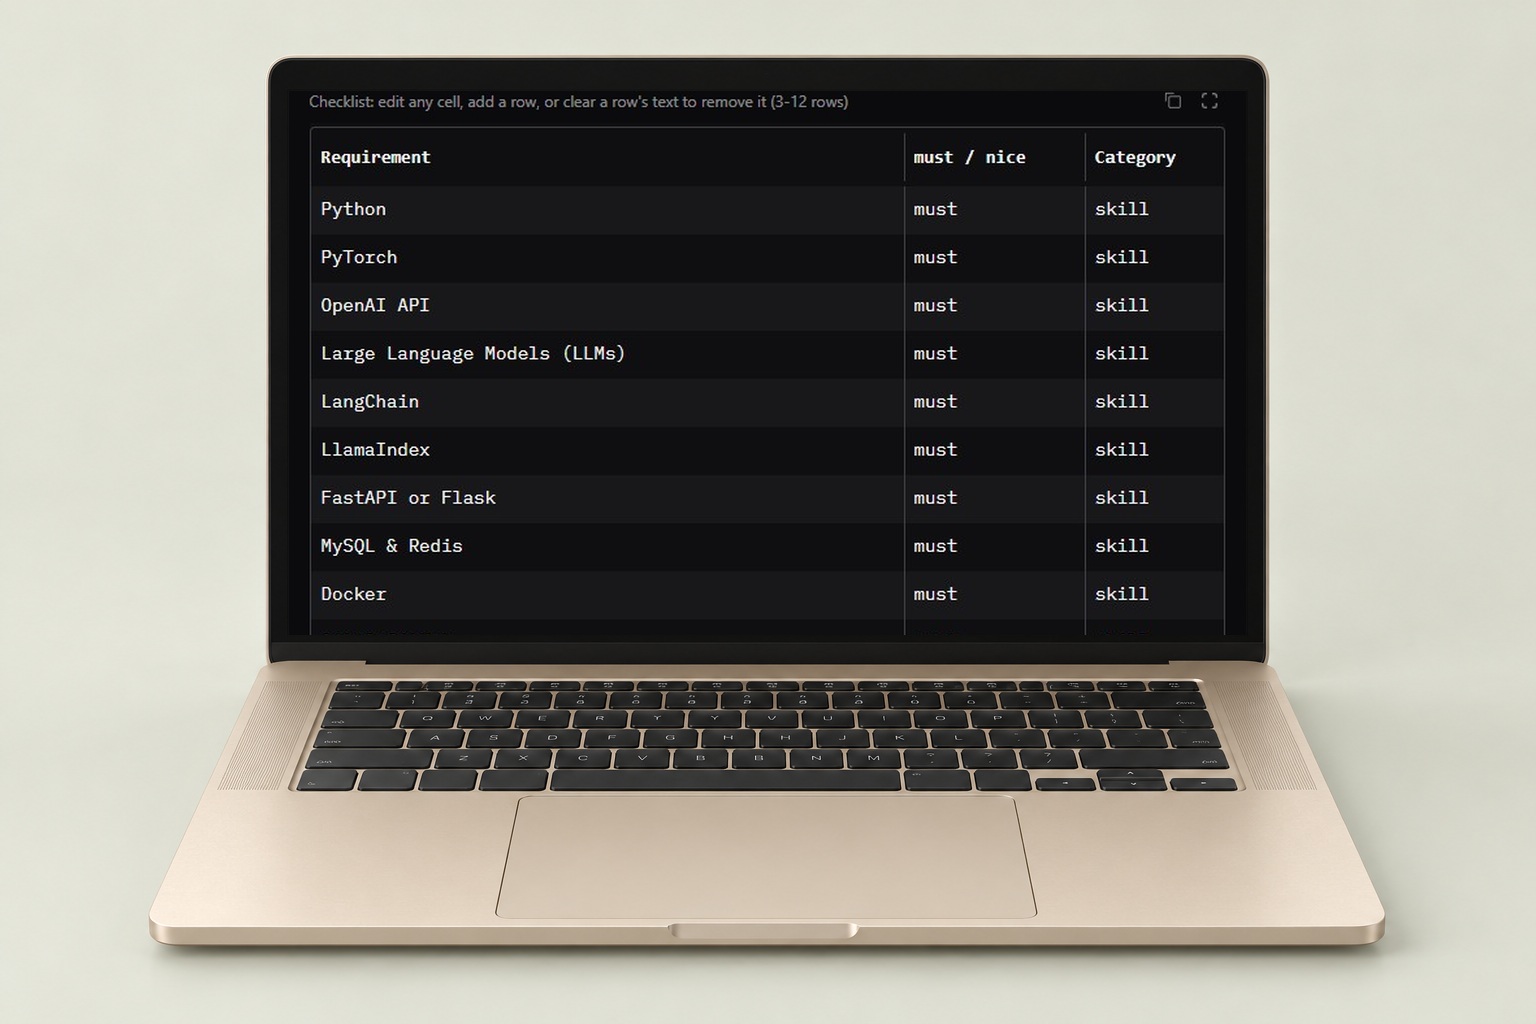
A checklist you can inspect.
The job description becomes an editable requirement list before screening begins.
View detail ↗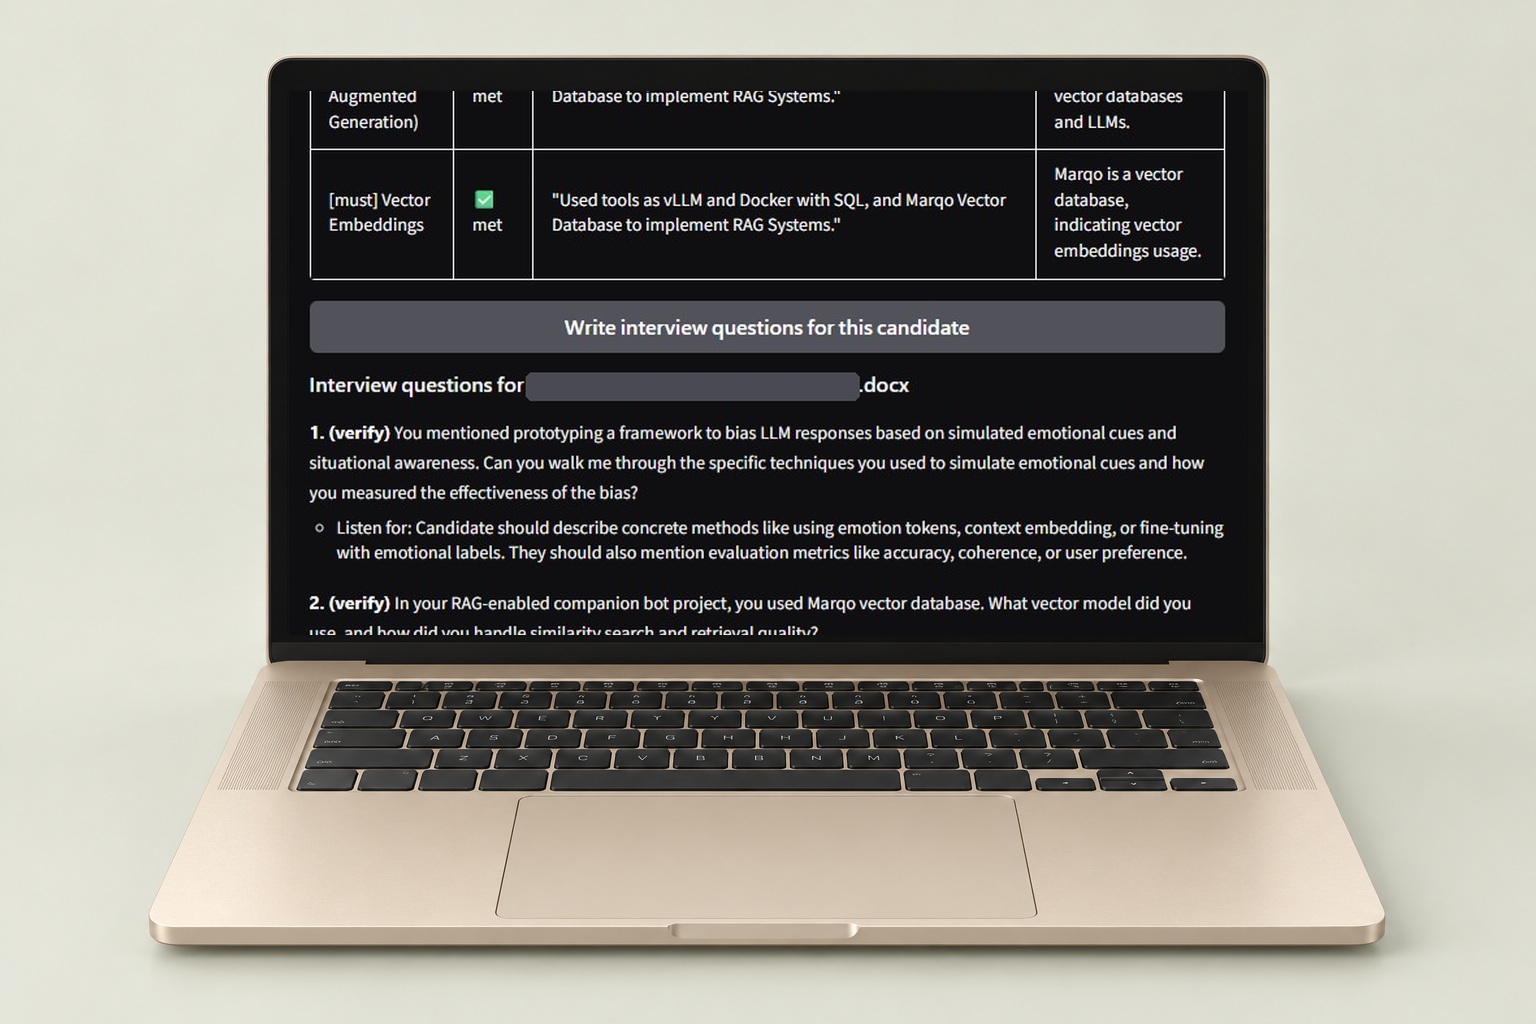
The reason behind the score.
Requirement verdicts, supporting quotes and interview questions keep the assessment inspectable.
View detail ↗My contribution, evidence and current limitations +
I fine-tuned Qwen3-4B with QLoRA, served it locally with llama.cpp, and separated model judgements from scoring. The model proposes a verdict and a quote. Python checks the quote and calculates the weighted score.
Saved results on 58 held-out synthetic resumes across 10 job descriptions show verdict agreement improving from 80% to 92%, while unsupported quotes fell from 6% to 2%.
These are small, teacher-labelled synthetic tests. A separate real-resume check matched 63 of 85 verdicts across 10 pairs. Quote matching does not prove a candidate claim is true, and name-swap results do not establish that the system is bias-free.
A useful next study would expand independent human labels and examine failure cases on a broader set of resumes.